MyWare Scribe — transcription & diarization
Know who said what — without sending a second of audio anywhere.
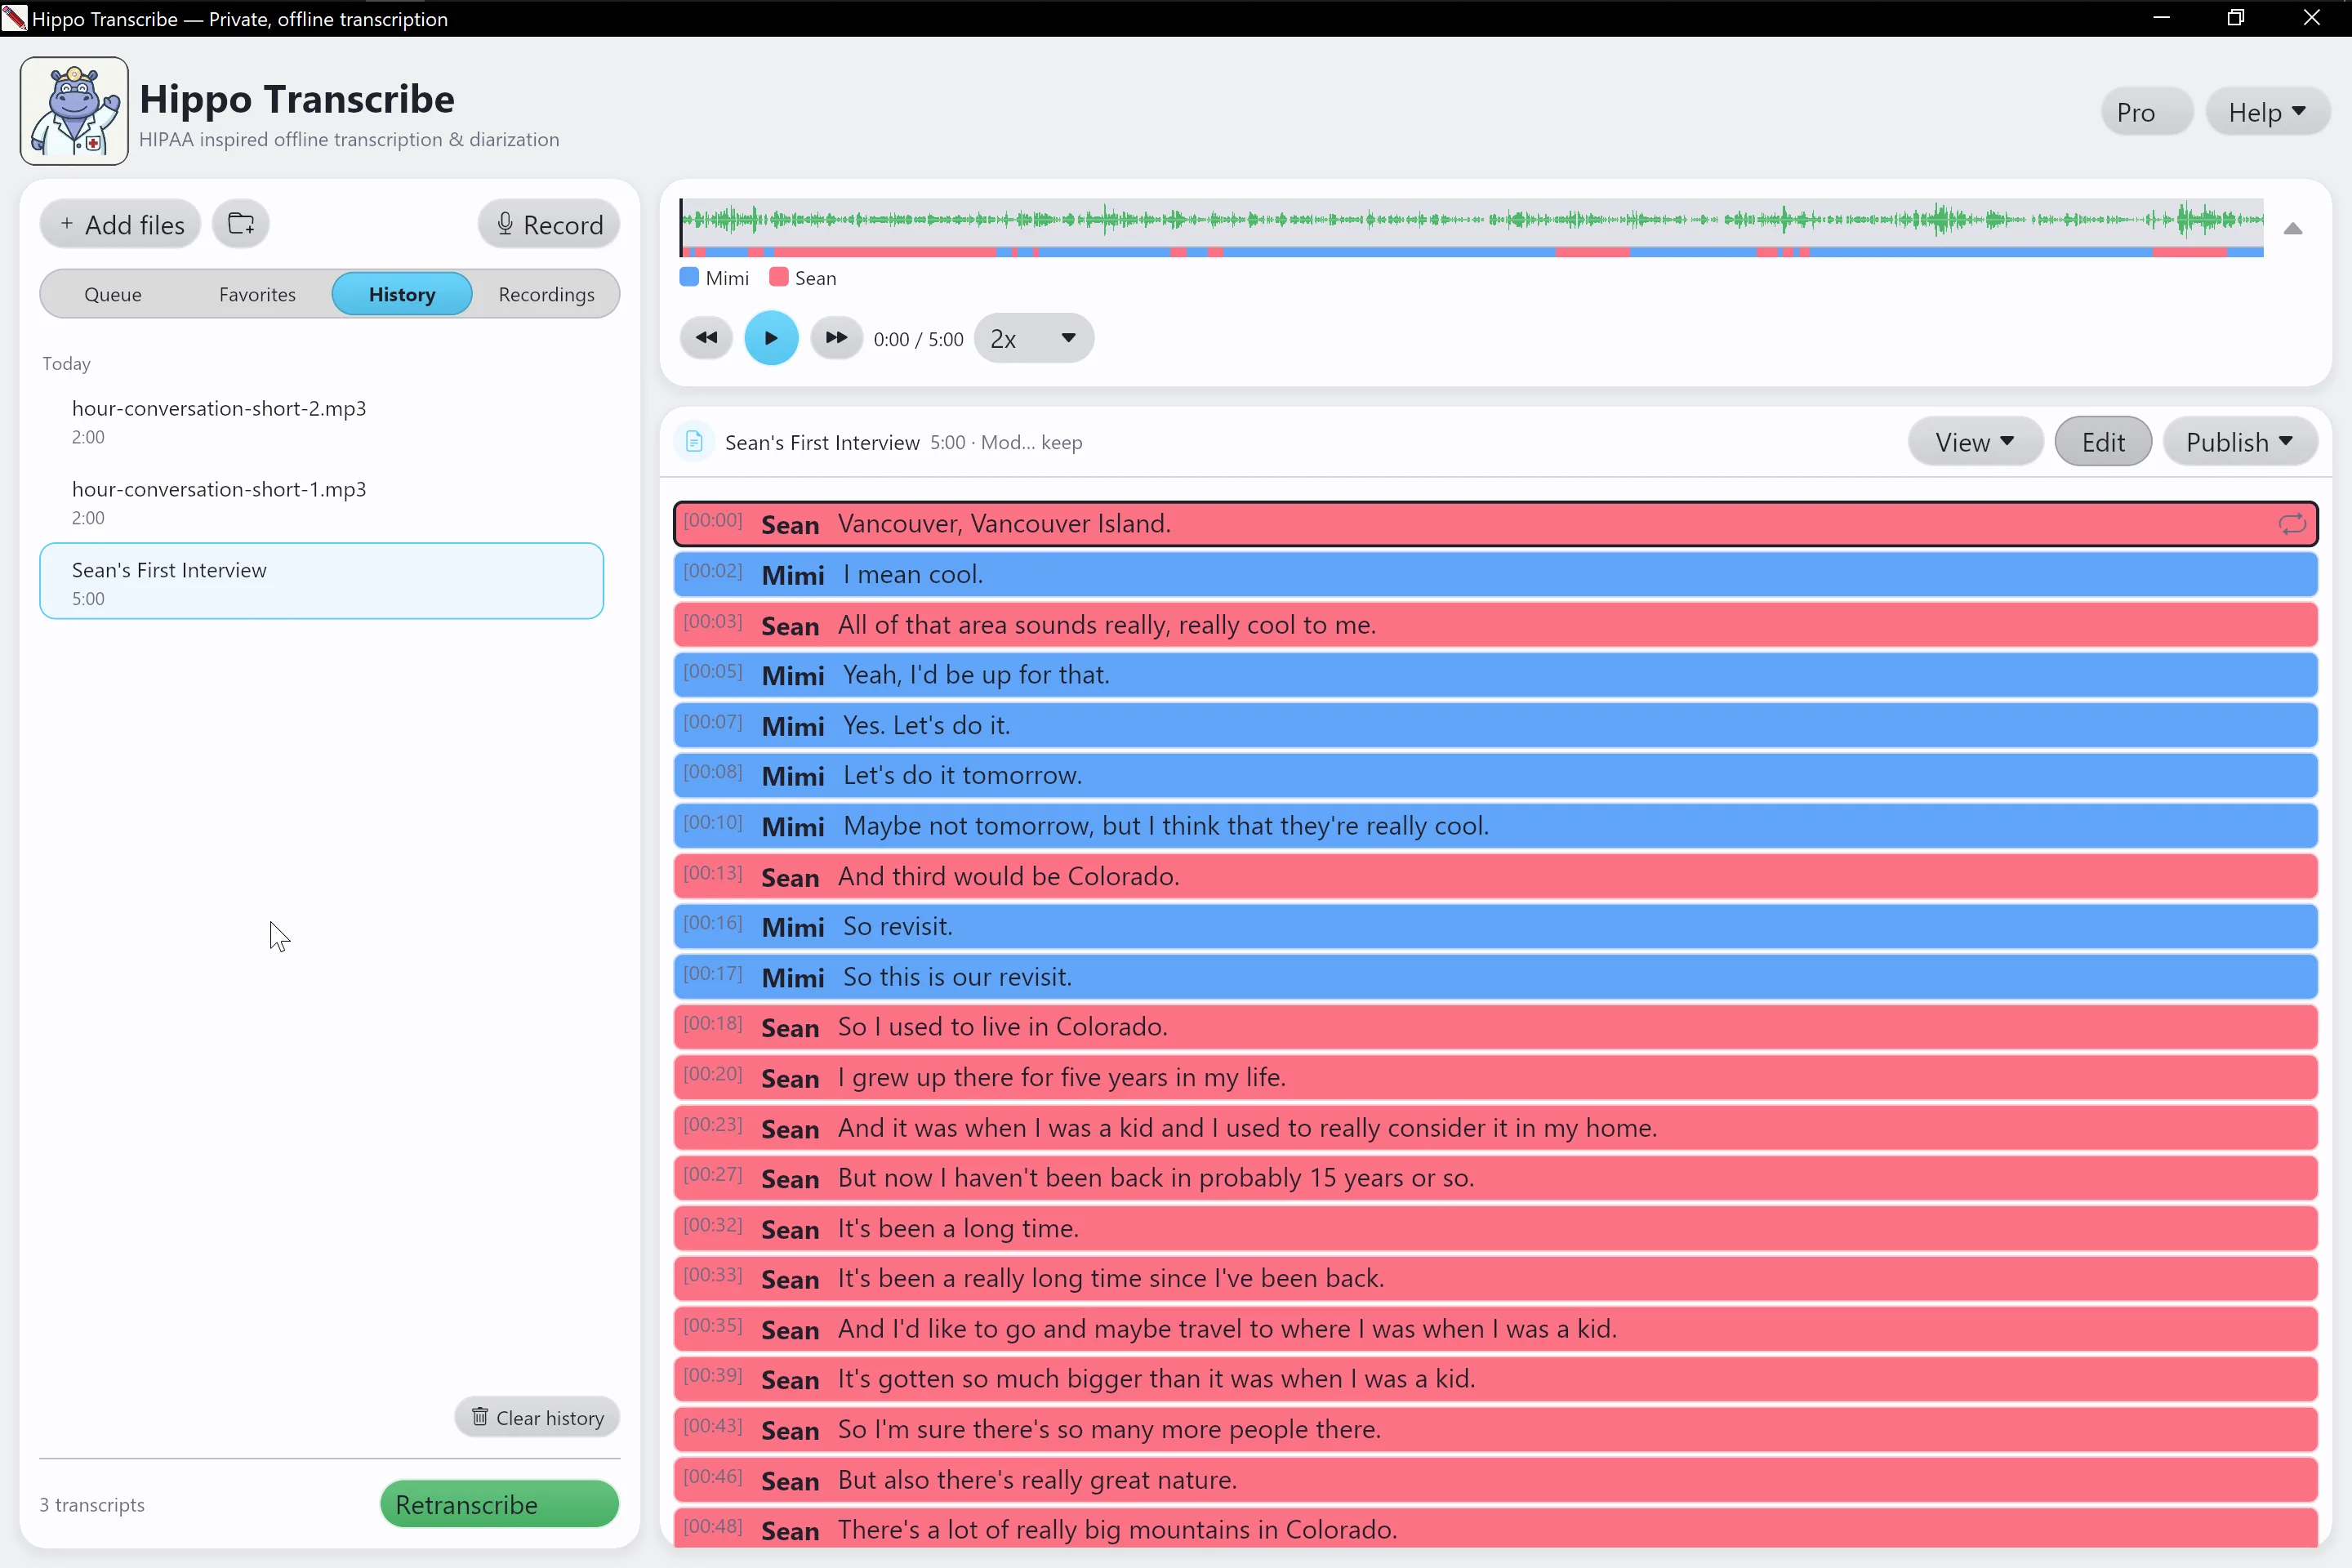
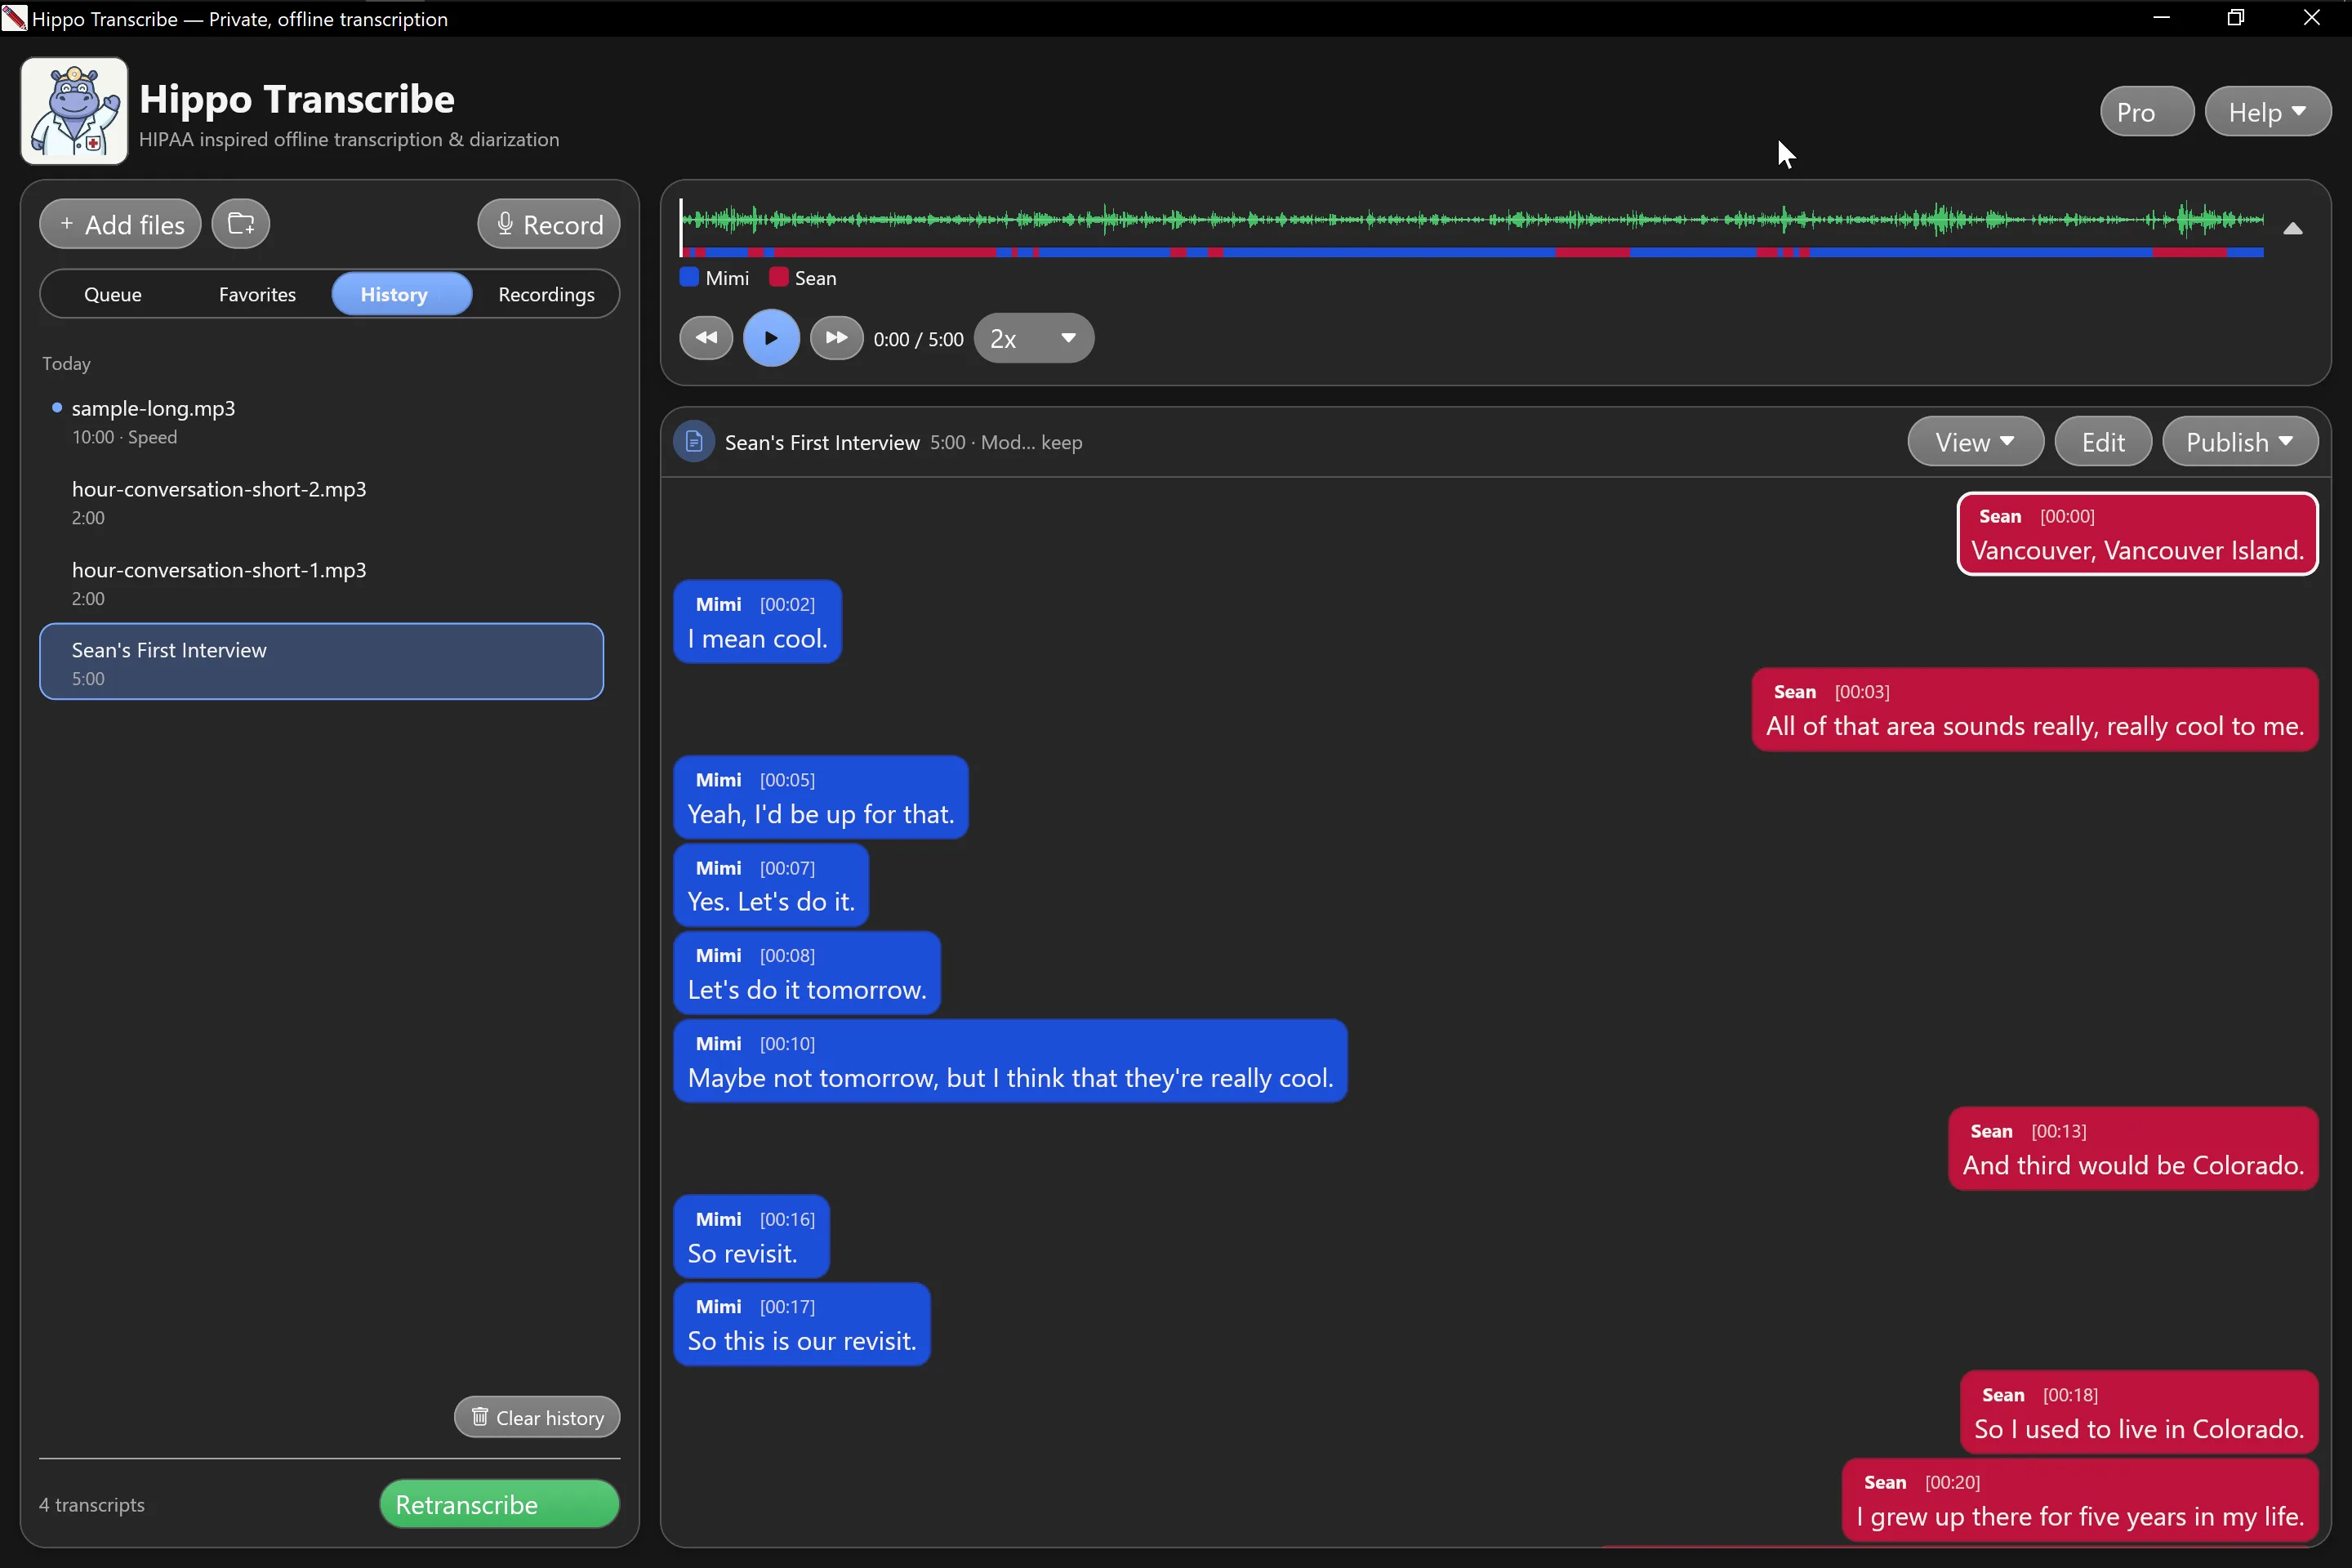
Scribe turns interviews, meetings and memos into transcripts with speaker labels and timestamps. Diarization and speech recognition run entirely on your machine, in a single native app with both a desktop window and a--cli mode. The name comes from HIPAA: the design follows its instincts — keep everything local — though Scribe makes no certification claim.
The application
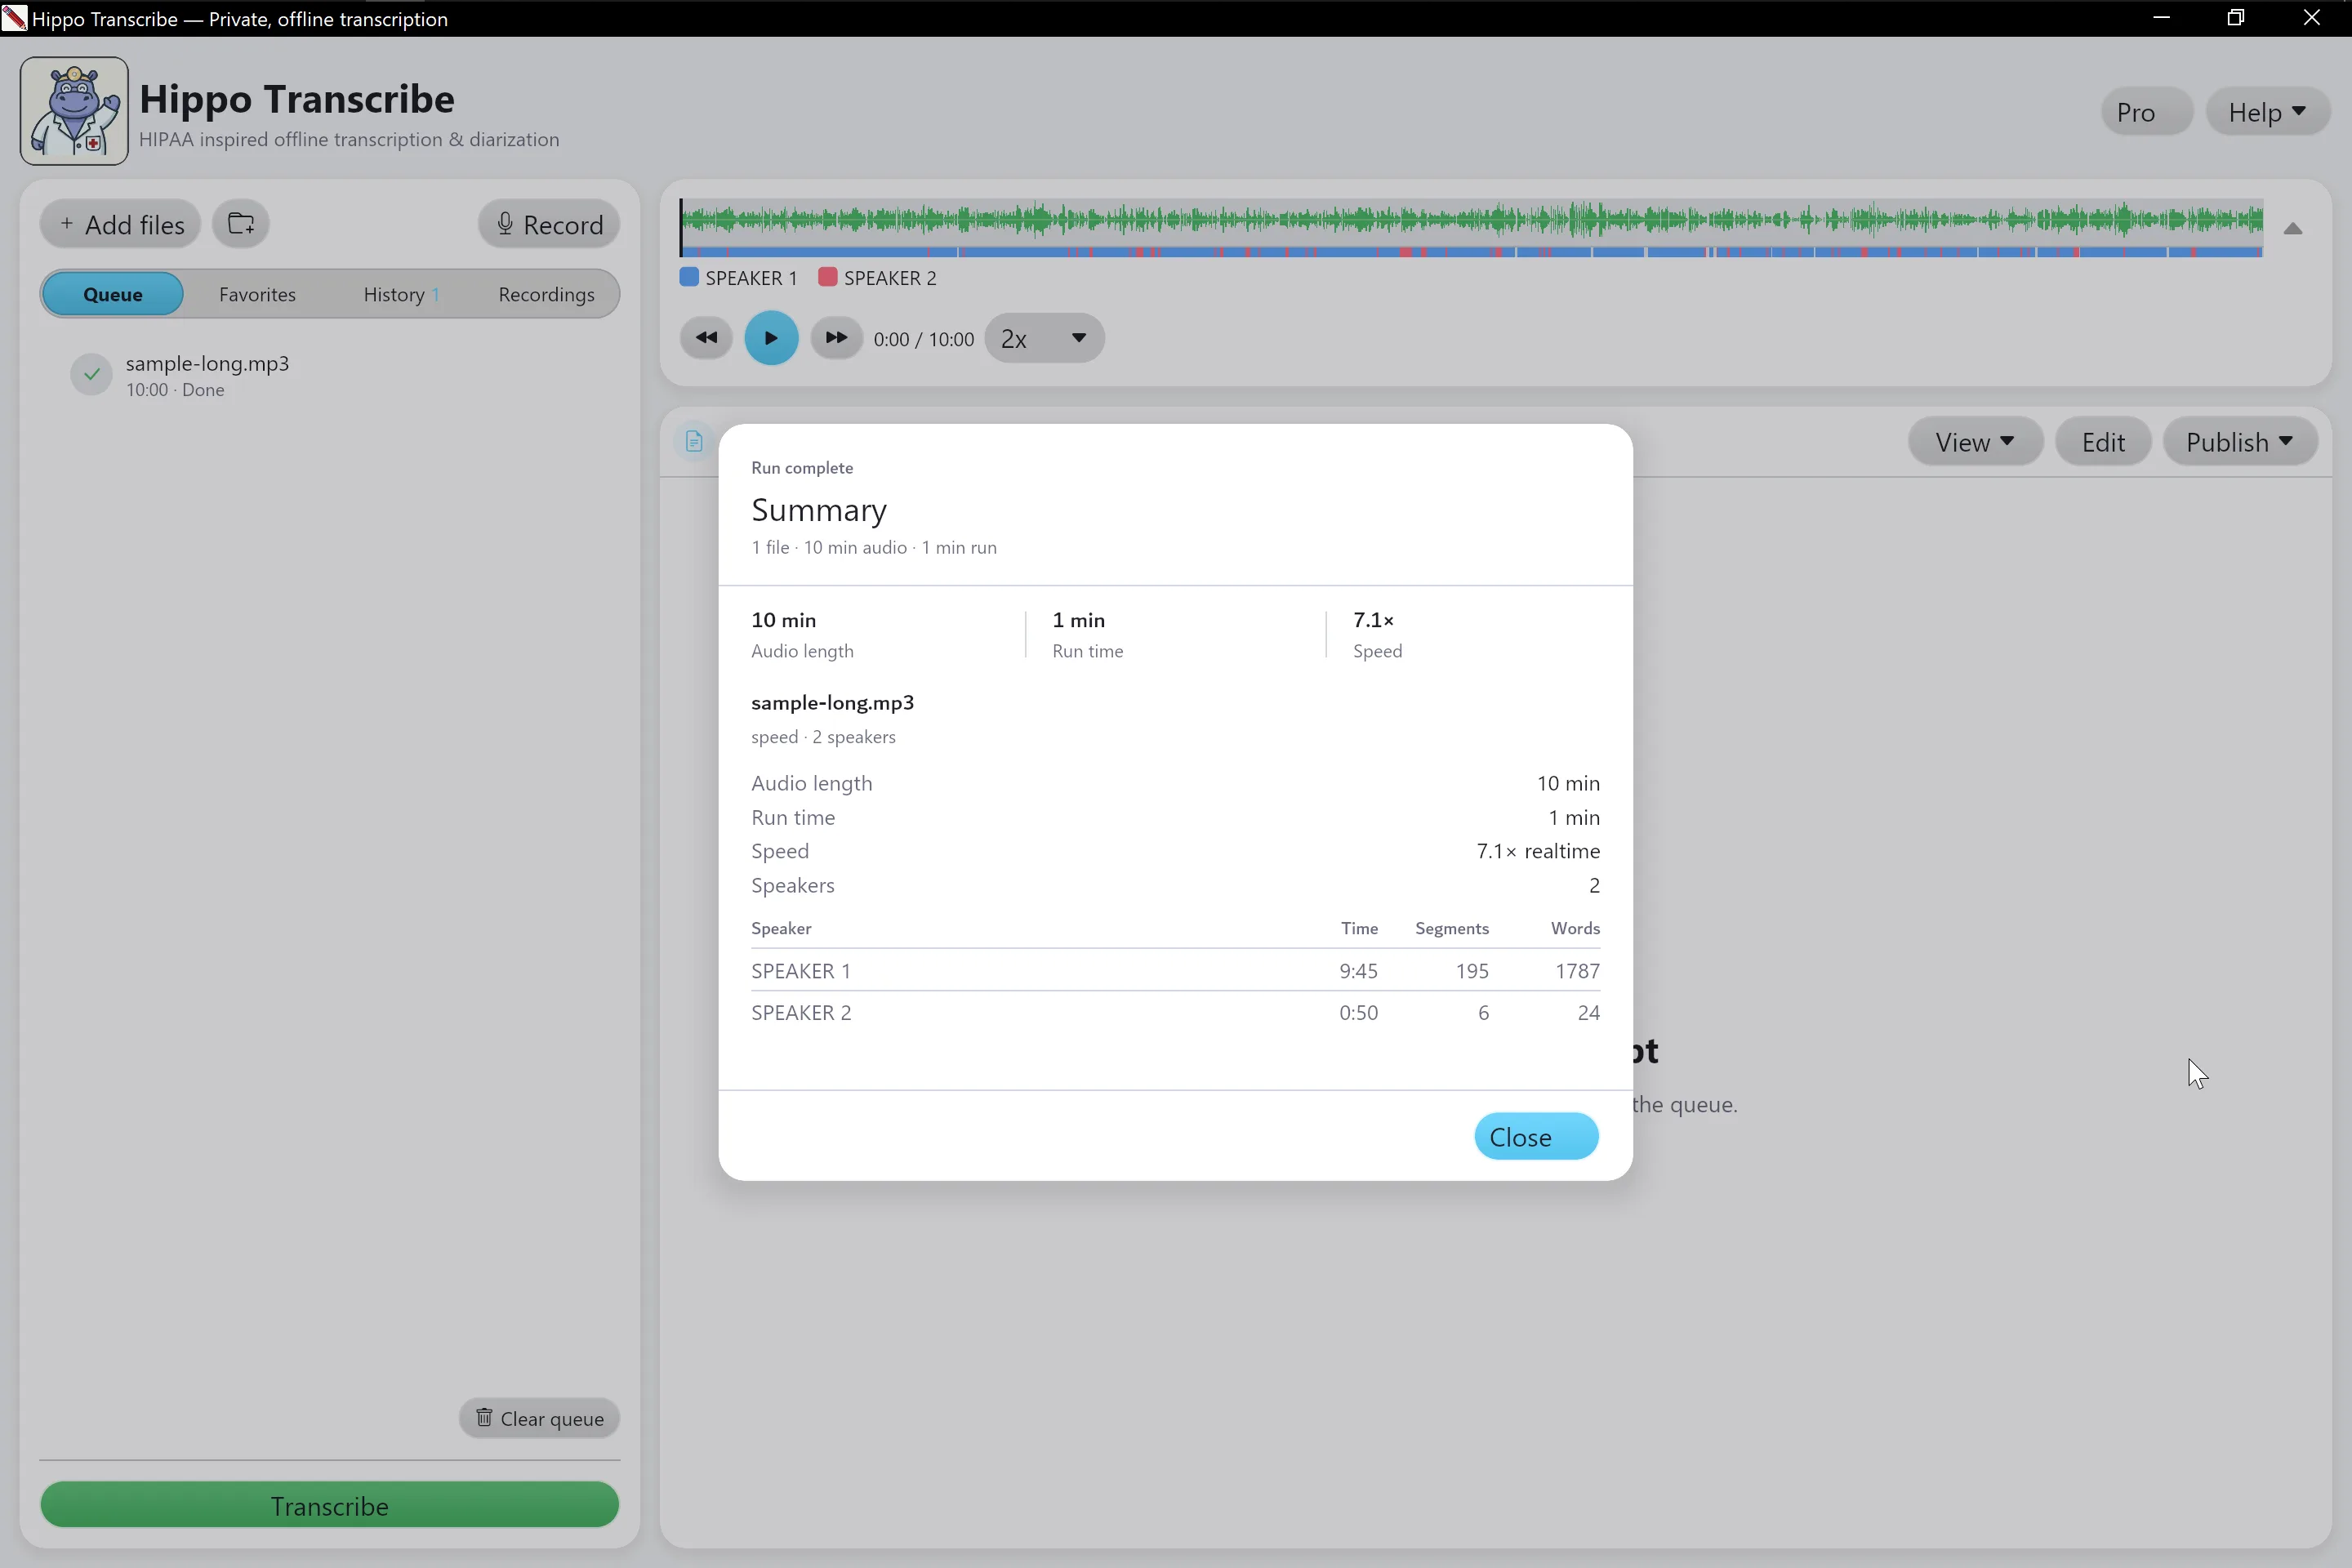
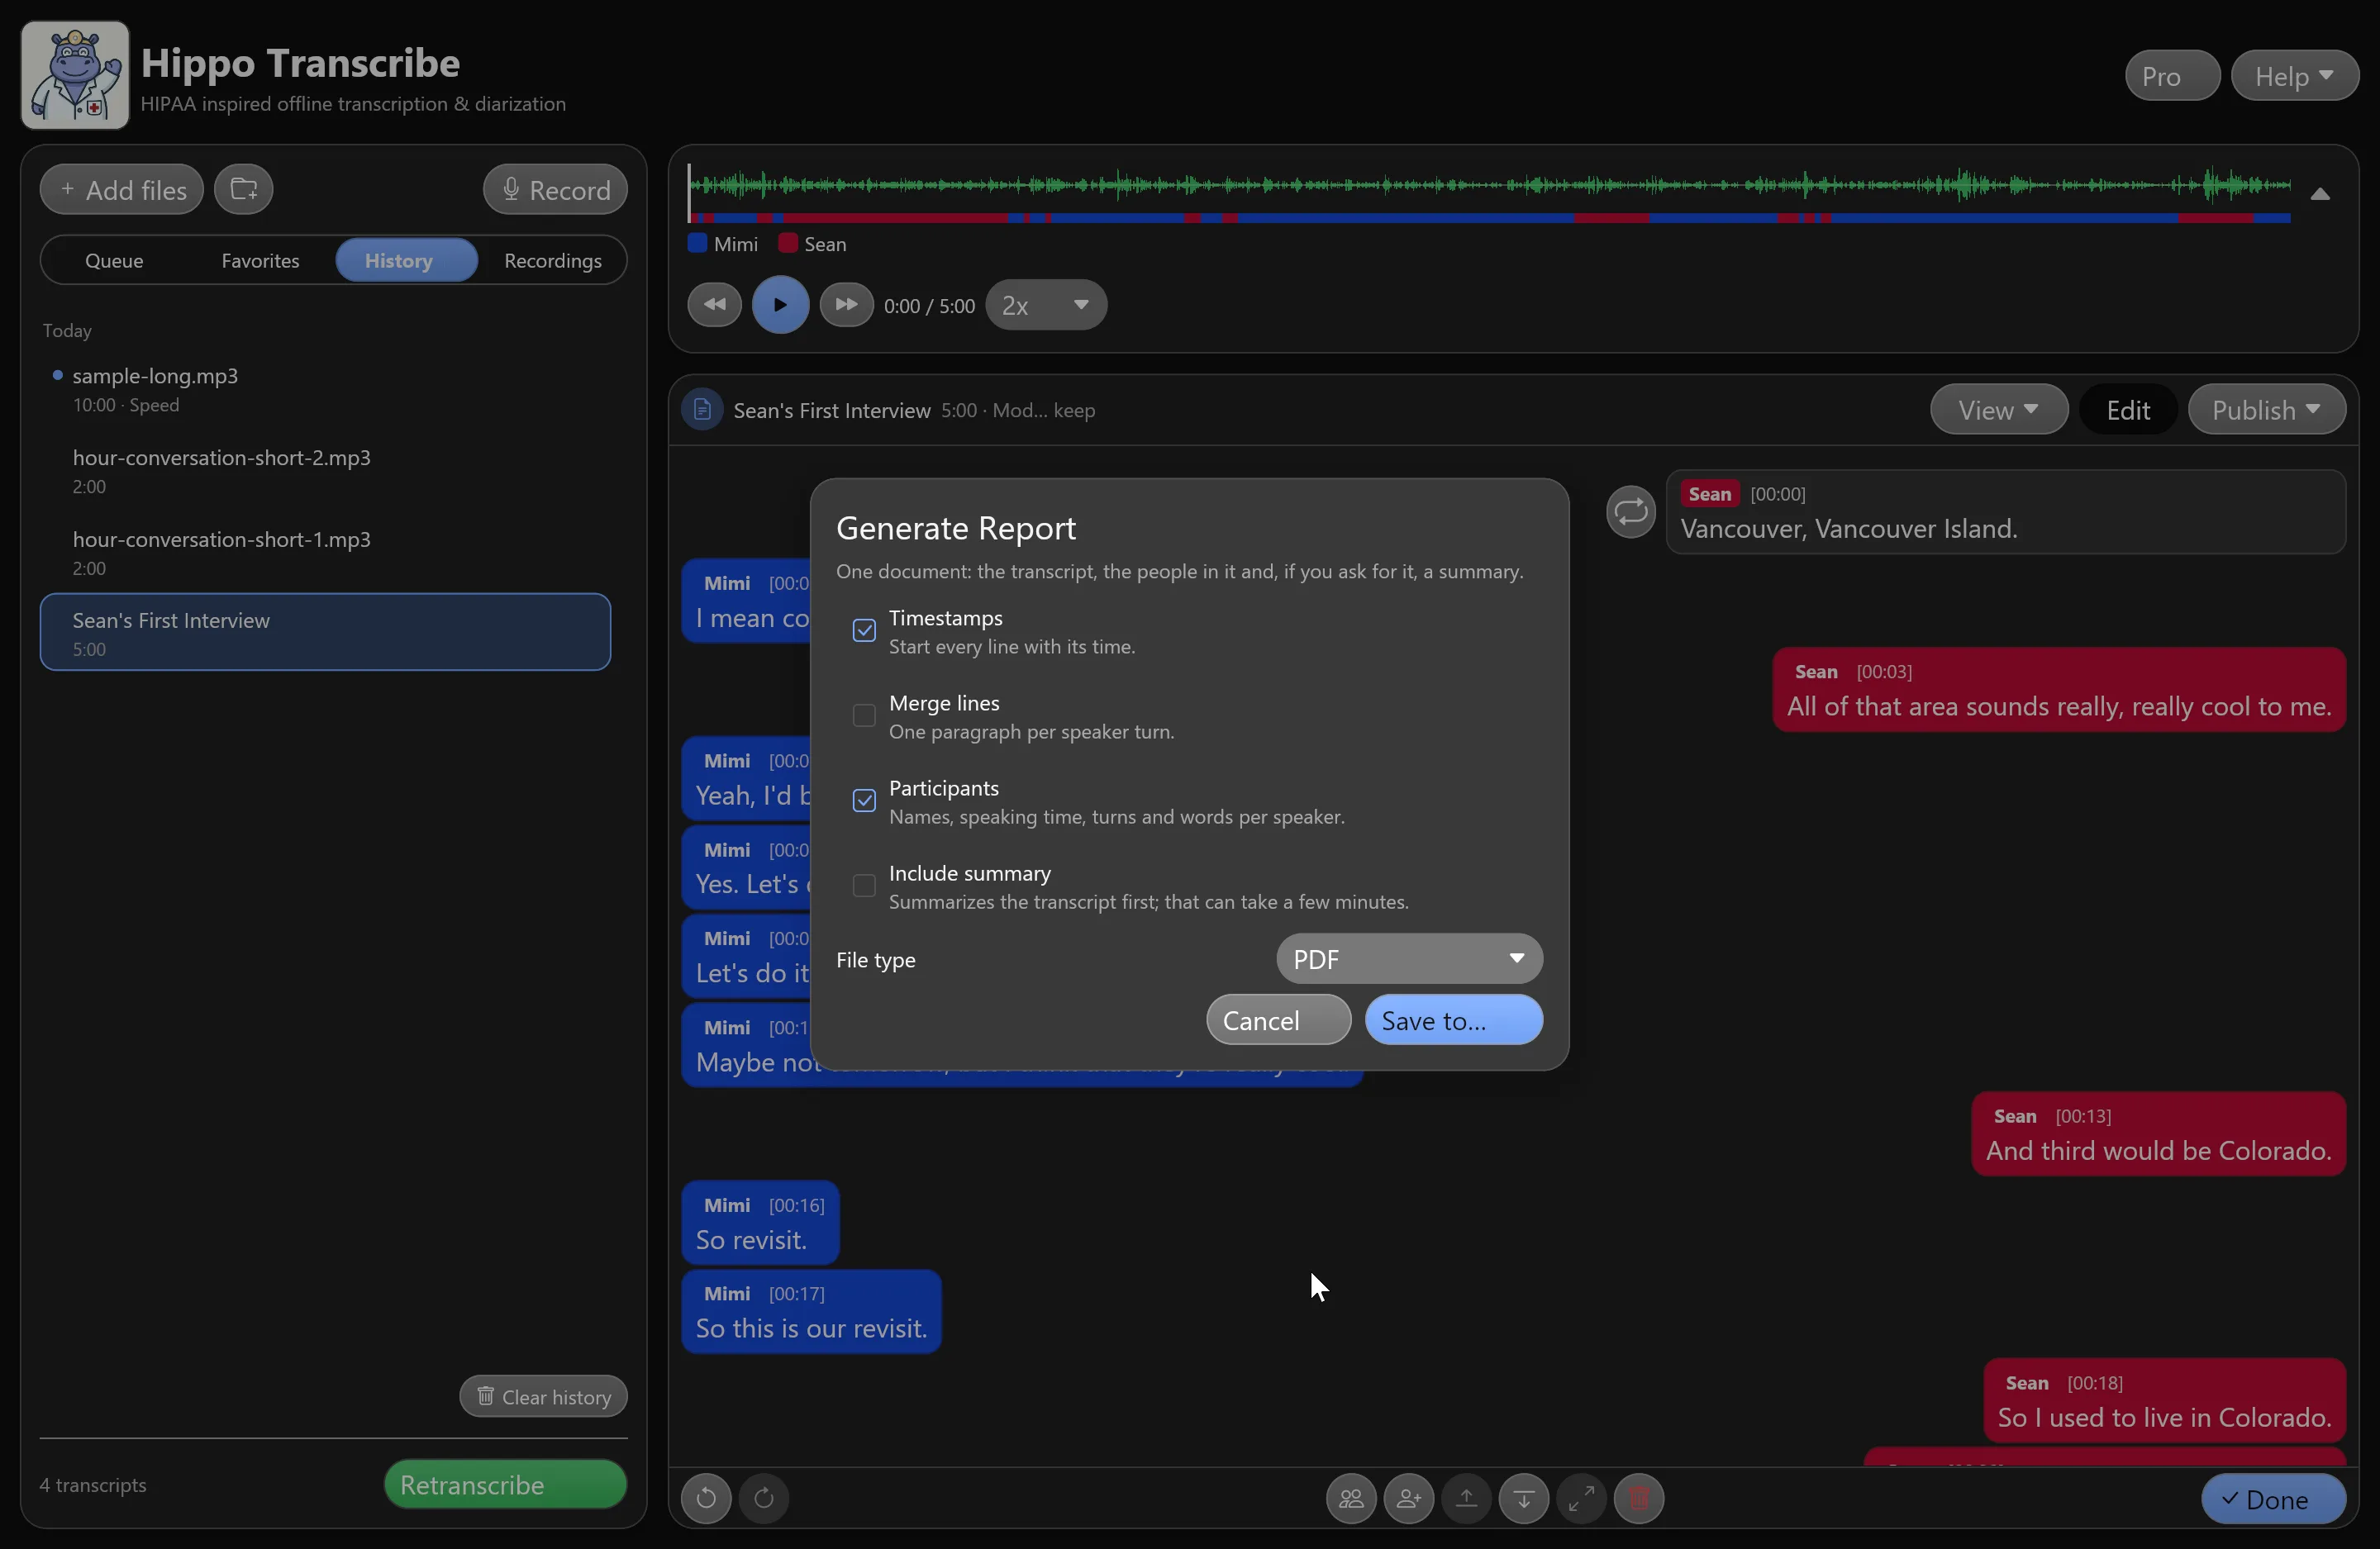
See it working.
Under the hood
A real diarization pipeline, not a demo.
Scribe finds who is speaking with sherpa-onnx (pyannote segmentation with wespeaker speaker embeddings), then transcribes with whisper.cpp. Turns are grouped into Whisper-sized windows and split at speaker changes using token timestamps — so labels survive long passages, not just clean turn-taking.
- PresetsSpeed (whisper tiny) is the default and the free tier's model.Balanced (small) and Accuracy (large-v3-turbo) are Pro. Every preset is multilingual; the language auto-detects or can be pinned.
- SpeakersYou set the speaker count. One speaker skips diarization entirely; two or more runs the full speaker pipeline. Speaker labels can be renamed and are written back to the transcript file.
- RecordingRecord from the microphone straight into a transcript — a two-second countdown, a live level meter, and stopping transcribes the take immediately.
- ExportsPlain text, SubRip and WebVTT subtitles, Markdown, CSV, Word and JSON — plus the Publish report (PDF, Word or text) with a participants section and an optional on-device summary.
- VocabularyA custom vocabulary list teaches the decoder your names, acronyms and jargon; replacement pairs fix recurring mishearings after the fact.
- CLI
myware-scribe --cli audio.mp3 --preset accuracy— batch multiple files, pin a language, stream progress as JSON events, and check or download models from scripts and cron. - AccelerationRuns on CPU everywhere. GPU via Vulkan is an opt-in Pro feature on Windows/Linux (and Metal on macOS builds), calibrated against your machine with an automatic fallback to CPU.
Privacy
Where the data goes: nowhere.
Audio, transcripts, diarization caches, models and settings stay on the machine that runs Scribe. There is no cloud service, no account and no telemetry. The app touches the network twice in its life: to download the models once (resumable, checksum-verified), and to confirm a Pro purchase. Nothing about your audio or transcripts is part of either call.
- No audio leaves
- Decode, diarization, recognition, export — all of it happens on your hardware.
- Checksummed models
- Model files are pinned by name, size and SHA-256; a bad or partial download is refused.
- Logs without content
- Diagnostic logs record models, backends and error messages — never audio, transcript text or file paths.
Free & Pro
The free tier is the full pipeline.
Free is not a timed trial: the Speed preset, one speaker, one file per run, unlimited files and audio length, microphone recording, search, copy and the automatic plain-text transcript — forever. Pro is a one-time purchase that adds the heavier lifting.
Free
Speed preset · one speaker · single-file runs · mic recording · search & copy · automatic .txt transcript
Pro — one-time purchase
Balanced & Accuracy presets · speaker diarization and labels · batch runs · transcript editing · audio playback · GPU acceleration · Favorites · every export and the Publish report.